<p>AWS Glue Data Catalog now supports automatic table optimization for Apache Iceberg tables in the US West (N. California) Region. Apache Iceberg is an open table format that delivers fast query performance over large tables in data lakes. With this launch, you can enable table optimization for individual tables or for all tables in your Data Catalog.</p>
<p>Apache Iceberg tables accumulate small files, snapshots, and unreferenced files with every write, which slows queries and increases storage costs over time. Table optimization continuously monitors your tables to compact small files in the background, remove snapshots that are past your retention settings, and delete unreferenced files that are no longer needed. You can monitor each run from the AWS Glue console, Amazon CloudWatch metrics, and logs.</p>
<p>You can enable table optimization using the AWS Glue console, AWS CLI, or AWS SDKs. For the full list of Regions where table optimization is available, see <a href="https://docs.aws.amazon.com/glue/latest/dg/regions-optimizers.html">Supported Regions for table optimizers</a>. To learn more, see <a href="https://docs.aws.amazon.com/glue/latest/dg/table-optimizers.html">Optimizing Iceberg tables</a> in the AWS Glue Developer Guide. To get started, visit the <a href="https://aws.amazon.com/glue/">AWS Glue product page</a>.</p>
AWS Glue Data Catalog now supports Apache Iceberg table optimization in the US West (N. California) Region
From the official release
This is a short excerpt. Read the full announcement on the official source.
Continue on aws.amazon.com → (opens in a new window)Related stories

Lakebase branching for CI/CD: lessons from 100 PR databases
Databricks Blog
The problem: testing against production data shouldn't take over 30 minutesSnorkel...

Build a Validated Kubernetes Runtime for NVIDIA Dynamo
NVIDIA Developer Blog
Teams building AI applications need a repeatable path from a model configuration to a working inference endpoint. NVIDIA Dynamo is a distributed inference... Teams building AI applications need a repeatable path from a model configuration to a working inference endpoint. NVIDIA D

Databricks and SAP unleash end-to-end data & AI capabilities to level up enterprise AI transformation
Databricks Blog
Today's AI models are more capable than ever. What they still lack is the business...
Amazon Bedrock expands API support and introduces Cross-Region Inferencing for OpenAI models in AWS GovCloud (US)
AWS What’s New
Amazon Bedrock now supports the OpenAI GPT-5.6 models (Terra and Luna) on the bedrock-runtime endpoint, with support for the Responses, Converse, and Chat Completions APIs in AWS GovCloud (US). It also adds support for Cross-Region Inference, allowing customers to use Cross-Regio

Run AI Models for Edge Application Development with Just a Few Commands
NVIDIA Developer Blog
AI is expanding beyond the data center as developers build a new generation of agents to act at the edge: monitoring driver attention and cabin conditions,... AI is expanding beyond the data center as developers build a new generation of agents to act at the edge: monitoring driv
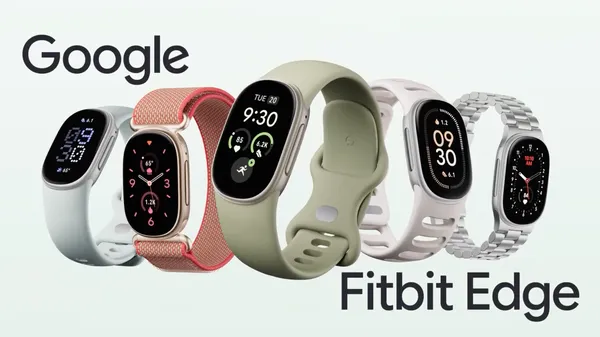
Google Fitbit Edge: On shelves now
Google Fitbit Blog
Shop the new Google Fitbit Edge featuring a bright, large display and physical side buttons for easy control. Upgrade your fitness tracker today.