Data teams often maintain uniqueness guarantees in their pipelines, but without a flexible way to represent all of them in the table schema, users and tools cannot discover them and the query optimizer cannot safely leverage them. Business entities often have more than one value, or combination of values, known to be unique: a users table might use user_id as its primary row identifier while its data model also records separate uniqueness guarantees for username, an email address, and (workspace_id, external_user_id).
Official announcementDatabricks Blog
Declare and optimize with UNIQUE constraints on Databricks

From the official release
This is a short excerpt. Read the full announcement on the official source.
Continue on databricks.com → (opens in a new window)Related stories
Official announcement
Fuel Every Agent and App With Data That Keeps Pace
Snowflake Blog
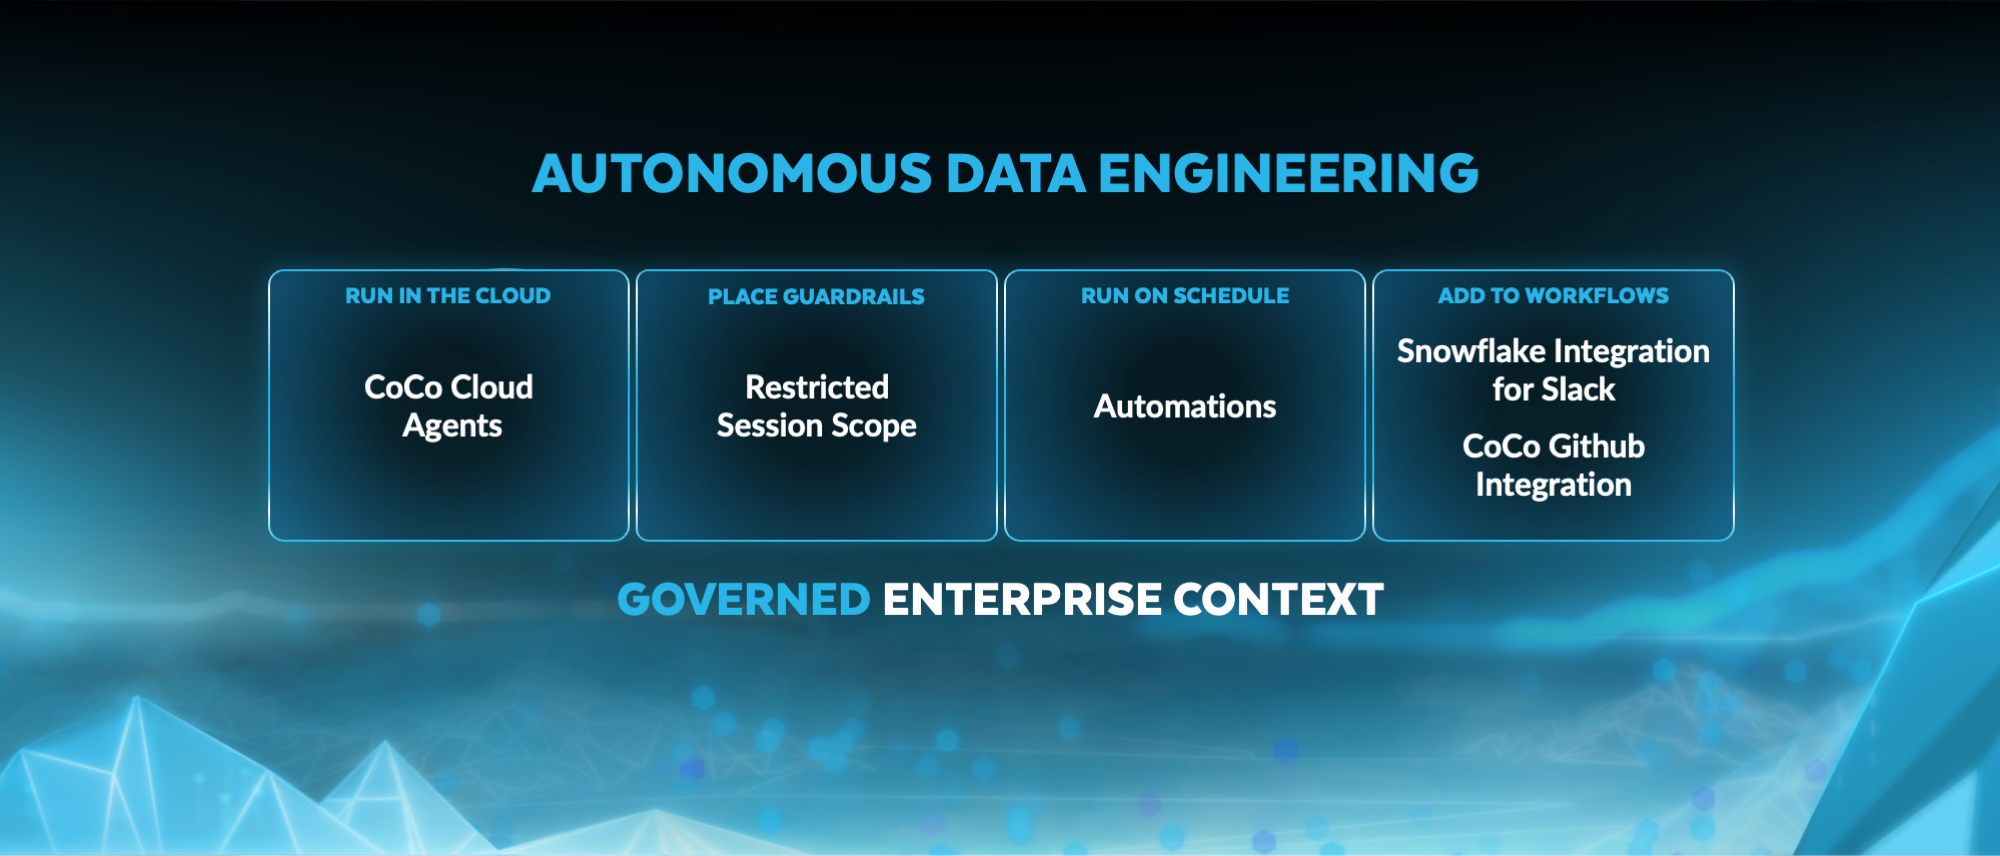
Most companies today are working hard to decide which AI agents and applications to build. But whether their data strategy will keep up, that's another matter entirely. An agent that provides answers based on outdated numbers or an app that can't see an order a customer placed fi
Official announcement
Cortex Training: Serverless Fine-Tuning for Open-Weight LLMs
Snowflake Blog
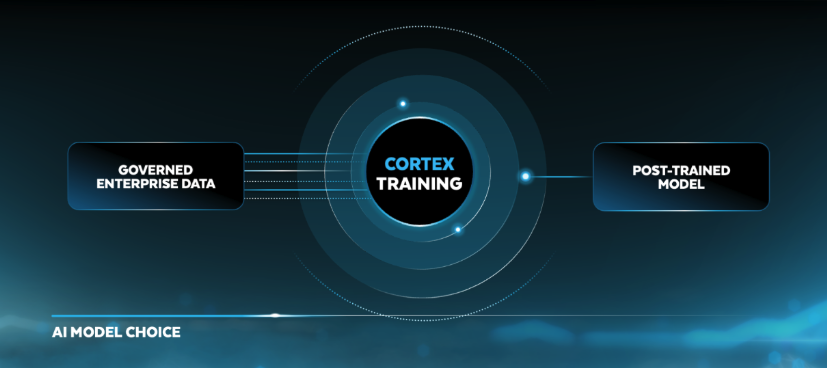
Successful model customization starts with high-quality training data. Snowflake’s data platform enables teams to clean, filter, enrich and label enterprise data — both structured and unstructured — into training-ready data sets with Cortex AI Functions, SQL and Snowpark. Cortex
Official announcement
Real-Time Analytics on Snowflake: Stream, Transform, Serve
Snowflake Blog
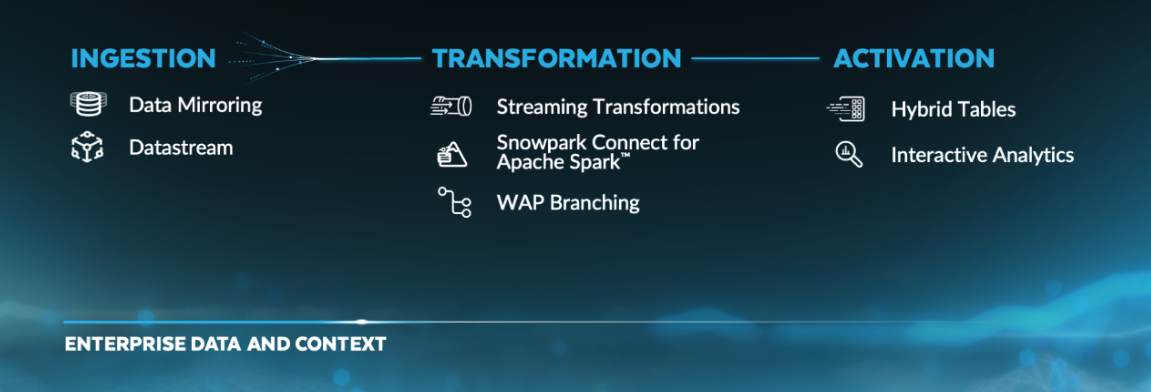
Every customer interaction is a chance to either earn trust or lose attention. To stay competitive, businesses need to act before that interaction ends. A financial services team needs the latest market data to discuss portfolio adjustments with their clients. A network operation

Official announcement
Keep Distributed Training Running with Automated Workload Recovery
NVIDIA Developer Blog
As distributed AI training scales, failures across hardware and software dependencies increasingly disrupt training progress, making fast, reliable recovery... As distributed AI training scales, failures across hardware and software dependencies increasingly disrupt training prog

Official announcement
Diagnose Distributed AI Workload Failures with NVIDIA Attribution
NVIDIA Developer Blog
In distributed AI workloads, a single error can produce a cascade of symptoms. A GPU or fabric event may surface as NCCL errors on other ranks, scheduler state... In distributed AI workloads, a single error can produce a cascade of symptoms. A GPU or fabric event may surface as N

Official announcement
StateBench: Testing how language models track state changes over long documents
Hugging Face Blog
a]:hidden" StateBench: Testing how language models track state changes over long documents Enterprise Article Published November 3, 2026 Upvote 5 Kyle Wiggers Ai2Comms Follow allenai :last child]:mb 0" 📄 Tech Report 🤗 Data 💻 Code We’re introducing StateBench , a benchmark for long context state tracking —how well...