Key takeaways 7 min read
Official announcementDell Blog
Faster GPUs and Smaller Caches Raise the Bar for Storage
Dell PowerScale, a storage engine within the Dell AI Data Platform, clears it — cutting time to first token by up to 13.6× on NVIDIA GB300.

-
KV-efficient models and faster GPUs don’t eliminate the need for storage-backed KV cache. Longer contexts and more agents per GPU mean more KV cache traffic to serve.
- In our testing with KV-efficient models on NVIDIA GB300 GPUs, Dell PowerScale — a storage engine within the Dell AI Data Platform — reduced mean time to first token by up to 13.6×, mean end-to-end latency by up to 8.1× and delivered up to 7.3× higher throughput.¹
- Recomputation on four GPUs plateaued at roughly 8K–14K tokens/s, while PowerScale retrieval kept scaling to 78.9K tokens/s at 128K-token context.
- Get more from the accelerators you already run: higher throughput and lower latency from the same GPUs, because long-context prompts are served from storage instead of recomputed.
KV cache offloading put storage directly on the inference path. Instead of holding key-value state in GPU memory or recomputing it on every request, the inference stack persists that state to storage and retrieves it when context is reused. We have written before about the scalable, persistent, RDMA-enabled architecture that makes this work across Dell storage engines. Storage performance became inference performance.
Two trends are now reshaping what that storage layer must deliver. Multi-Latent Attention, sparse attention and KV cache compression are shrinking the KV cache per token, enabling contexts of up to one million tokens. At the same time, NVIDIA Blackwell and the upcoming Vera Rubin architectures deliver considerably higher compute performance and memory bandwidth. Both trends increase KV cache traffic: faster GPUs generate and consume cache data at higher rates, while smaller caches enable longer contexts and more agents per GPU.
So the question becomes a practical one: can storage keep up with that pace of change, and does KV cache offloading to shared storage still play a role in AI inference?
Storage for AI inference, tested on KV-efficient models
We benchmarked PowerScale-backed KV cache on NVIDIA GB300 GPUs running Kimi-K2.7-Code and DeepSeek-V4-Pro, using an open-source inference stack.
Testbed
-
Compute: Dell PowerEdge XE9712 (NVIDIA GB300 NVL72), four GPUs, BlueField-3 for storage networking
- Storage: Three Dell PowerScale F710 nodes, GPUDirect Storage over NFS/RDMA
- Software: vLLM, LMCache and NVIDIA NIXL, all open source
- Workload: 8K–128K-token input, 1,024-token output, 32 and 64 concurrent requests
Each configuration ran twice on an identical request sequence: a cold run that computed KV cache on the GPUs and persisted it to PowerScale, and a warm run that retrieved it from PowerScale at a 100% cache hit rate.
The difference isolates the storage path. Full configuration and methodology for our testing is in the technical report, co-authored with Gaurav Chawla and Boris Glimcher.
Kimi-K2.7-Code
Kimi-K2.7-Code is a one-trillion-parameter mixture-of-experts model (~32B active parameters) with a 262K-token context window and MLA-based attention that shrinks the KV cache.
-
Across the 32K to 128K range, KV cache reuse from PowerScale reduced mean TTFT by up to 13.6× and increased total token throughput by up to 7.1×.
- The GPU-compute path reached a throughput knee at approximately 8K to 9.5K tokens/s. Beyond that point, longer context primarily increased latency rather than aggregate throughput — the four-GPU prefill pipeline was approaching saturation.
- The PowerScale retrieval path showed no equivalent plateau, continuing to scale to 58K tokens/s at 128K-token context.
- At 128K-token context, KV cache reuse reduced mean end-to-end latency by approximately 8×, translating directly into faster user-visible response times.
- Gains held across both concurrency levels. End-to-end latency and throughput gains grew with context length.
PowerScale KV cache reuse vs. GPU recomputation — Kimi-K2.7-Code
Concurrency
Input sequence length
Mean TTFT
Mean E2E latency
Token throughput
32
32K
9.1× lower
3.5× lower
3.5× higher
32
64K
13.6× lower
5.4× lower
5.4× higher
32
128K
9.8× lower
7.9× lower
6.7× higher
64
32K
12.6× lower
4.4× lower
4.5× higher
64
64K
8.2× lower
6.4× lower
5.4× higher
64
128K
8.6× lower
8.1× lower
7.1× higher
For long-context agentic workloads, PowerScale KV cache reuse moved the system out of a GPU-prefill-bound regime — continuing to scale well beyond the saturation point of the GPU-only path.
DeepSeek-V4-Pro
DeepSeek-V4-Pro uses hybrid attention to support up to one million tokens of context with a minimal KV cache footprint.
-
Across the 32K to 128K range, KV cache reuse from PowerScale reduced mean TTFT by up to 7.9× and increased total token throughput by up to 7.3×.
- The GPU-compute path reached a throughput knee at approximately 12K to 14K tokens/s. Beyond that point, throughput declined while latency increased sharply — long-context prefill had become the dominant bottleneck.
- The PowerScale retrieval path showed no observable throughput knee within the tested range, continuing to scale to 78.9K tokens/s at 128K-token context.
- At 128K-token context, KV cache reuse reduced mean end-to-end latency by up to 7.4×, translating directly into faster user-visible response completion.
- Gains held across both concurrency levels and grew with context length.
PowerScale KV cache reuse vs. GPU recomputation — DeepSeek-V4-Pro
Concurrency
Input sequence length
Mean TTFT
Mean E2E latency
Token throughput
32
32K
4.2× lower
2.3× lower
2.3× higher
32
64K
4.2× lower
3.3× lower
3.2× higher
32
128K
6.2× lower
7.0× lower
7.2× higher
64
32K
5.3× lower
3.2× lower
3.2× higher
64
64K
6.7× lower
4.3× lower
3.9× higher
64
128K
7.9× lower
7.4× lower
7.3× higher
Storage-backed KV cache reuse delivers substantial gains even against architectures purpose-built to minimize the cache.
Note: Performance results should not be considered final performance numbers. Dell continues to work closely with the vLLM, LMCache and NIXL communities to optimize the end-to-end KV cache offloading stack. Future software releases are expected to further improve both GPU utilization and storage retrieval performance.
What this means for customers
Agentic AI is pushing inference toward longer contexts and more concurrent agents on every GPU. Faster accelerators and KV-efficient models raise the bar for storage for AI inference. In our testing, Dell PowerScale kept scaling after GPU recomputation reached its ceiling.
For teams running agentic AI, that means:
-
Higher GPU efficiency. Serve long-context prompts from storage instead of recomputing them.
- Scale without proportional GPU growth. Grow context length and concurrency with storage.
- Faster responses. Lower time to first token and end-to-end latency for multi-turn agents and coding assistants.
And it runs on an open stack of vLLM, LMCache and NVIDIA NIXL, with PowerScale as a storage engine within the Dell AI Data Platform.
Explore the Dell AI Data Platform or talk to a Dell AI expert about your model mix, concurrency targets and context lengths to get started with KV cache offloading on Dell infrastructure.
Frequently asked questions
- Which storage platforms are best suited for AI training and inference workloads?
Evaluate on sustained throughput to keep accelerators fed, low-latency access paths such as GPUDirect Storage over RDMA, published benchmark evidence on current-generation accelerators and tested reference architectures. Dell PowerScale — a storage engine within the Dell AI Data Platform — has published results on NVIDIA GB300 systems showing mean time to first token reduced by up to 13.6×, mean end-to-end latency reduced by up to 8× and up to 7.3× higher throughput through KV cache reuse, measured on Kimi-K2.7-Code and DeepSeek-V4-Pro at up to 128K-token context.
- What is KV cache offloading, and why does it matter for AI inference?
When a large language model processes a prompt, it computes key-value state for every token. Every concurrent agent competes for finite GPU memory, forcing organizations to choose between lower concurrency, shorter context windows or additional GPUs. KV cache offloading persists that state to high-performance storage and retrieves it on subsequent requests, so the GPU does not repeatedly recompute long-context prompts.
- Do faster GPUs and KV-efficient models eliminate the need for storage-backed KV cache?
No. This testing used two architectures designed specifically to reduce KV cache footprint — one MLA-based, the other hybrid attention — and still measured substantial gains. Faster GPUs generate and consume KV cache data at unprecedented rates, while smaller caches enable longer contexts and greater agent density per GPU. Both trends increase the volume of KV cache traffic that must be served.
- What should enterprises look for in a data platform for agentic AI?
A platform that treats inference performance as a data problem: storage engines that serve long-context workloads without recomputation, data engines for processing, analytics and search, orchestration across the data lifecycle and cyber resilience embedded throughout. The Dell AI Data Platform is designed to add these capabilities to the environment an organization already runs.
- Does the inference software stack require proprietary Dell software?
No. The stack is vLLM, LMCache and NVIDIA NIXL — all open source. Dell optimizes and validates this stack across Dell compute and storage platforms and contributes improvements back upstream.
- How do these results apply to my workload?
The benchmark isolates the storage path by replaying an identical request sequence at a 100% KV cache hit rate, representing the reuse pattern common in coding assistants, multi-turn agents and shared-context deployments. Real-world benefit scales with how often your workloads reuse context, and latency and throughput gains grew as context length increased from 32K to 128K tokens. These results are based on internal Dell testing, September 2026. Actual results may vary.
1Based on Dell internal testing, September, 2026. Comparison is PowerScale KV cache reuse versus GPU recomputation of the same prompts on identical hardware, at a 100% cache hit rate. Cited maximums come from different test points: 13.6× TTFT and 8.1× end-to-end latency on Kimi-K2.7-Code, 7.3× throughput on DeepSeek-V4-Pro, across 32K–128K-token inputs at concurrency 32 and 64. Full configuration and methodology – Keeping Pace with GB300: Scaling Agentic AI Inference with Dell PowerScale KV-Cache. Actual results will vary based on model, context length, concurrency, cache hit rate, configuration, and workload.
Related stories

Official announcement
TensorRT Edge-LLM Completes the MLPerf Edge Agentic Benchmark 6.4x Faster on Jetson AGX Thor
NVIDIA Developer Blog
AI agents are moving from cloud data centers to vehicles, robots, and other edge devices. Unlike a chatbot that answers a single prompt, an agent works through... AI agents are moving from cloud data centers to vehicles, robots, and other edge devices. Unlike a chatbot that answe
Official announcement
Call of Duty: Modern Warfare 4: The Story So Far
Xbox WireMike Nelson, XBOX Wire Editor
The post Call of Duty: Modern Warfare 4: The Story So Far appeared first on XBOX Wire .

Official announcement
A Validated Path to Enterprise AI Governance with JFrog and Dell
Dell Blog
Build a governed AI software supply chain with JFrog, Dell AI Factory with NVIDIA, and Dell Automation Platform.

Official announcement
Two Texas Icons: How Dell Helps the San Antonio Stock Show & Rodeo Grow Its Mission
Dell Blog
The San Antonio Stock Show & Rodeo serves 20,000 Texas students a year. See how Dell Technologies keeps the event running and the mission growing.

Official announcement
Dell PowerStore AI Skills: Smarter Storage Operations
Dell Blog
See how AI skills with pstcli let admins manage Dell PowerStore in natural language – with faster health checks, performance analysis, and secure operations.
Official announcement
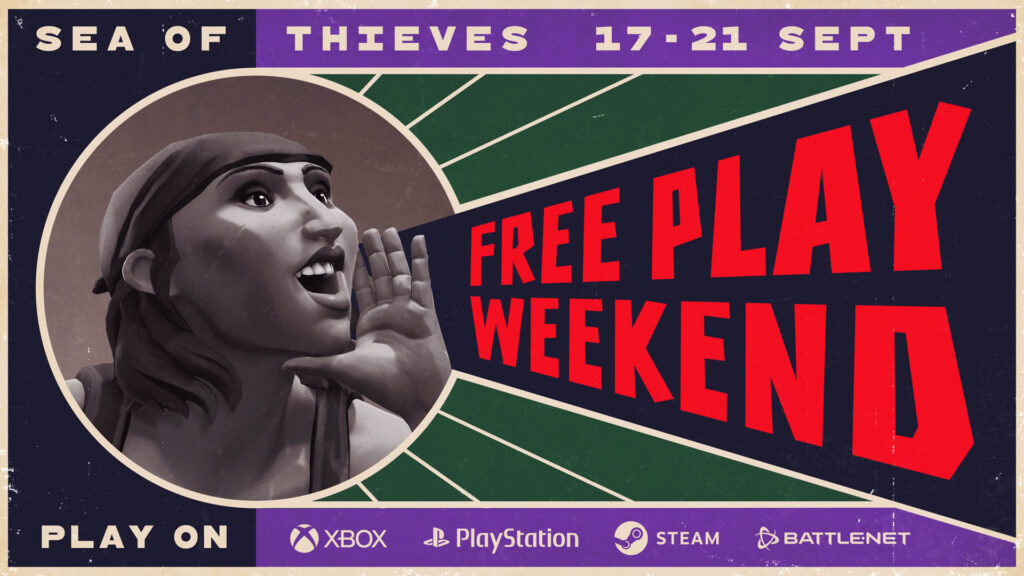
Sea of Thieves: Season 21, Talk Like a Pirate Day, New Rewards, Amazing Prizes and More!
Xbox WireJoe Skrebels, XBOX Wire Editor-in-Chief
Sea of Thieves : Season 21 is landing, and everyone’s welcome on the waves in time for Talk like a Pirate Day – we’re bringing new items, rewards, and sweepstakes for amazing prizes. And it all starts with a Free Play Weekend. From September 17 at 15:00 UTC (through to September