Generating tokens faster starts with identifying what limits inference performance. In the batch-size-1 evaluation of Ling-3.0-flash from Inclusion AI on NVIDIA DGX Spark, profiling showed that decoding was memory-bound: reading model weights drove execution time. Two operations stood out—the mixture-of-experts (MoE) computation and the output-layer projection that produces scores across the model’s vocabulary.
Official announcementNVIDIA Developer Blog
3 Ways to Boost MoE Inference on NVIDIA DGX Spark

From the official release
Those findings pointed to two ways to improve performance: reduce the weight traffic in each decode step and generate more tokens per verification round. This post examines three techniques that address those costs:
- Humming MXFP4 MoE kernels to improve execution of the routed-expert computation.
- Online FP8 quantization of the output layer, or LM head, to reduce its weight-read volume.
This is a short excerpt. Read the full announcement on the official source.
Continue on developer.nvidia.com → (opens in a new window)Related stories

Official announcement
Fine-Tuning NVIDIA Nemotron to Know Local Rules, Not Just Local Languages
NVIDIA Developer Blog
As AI adoption expands globally, people across languages and cultures are using it in more aspects of their daily lives. General-purpose language models serve... As AI adoption expands globally, people across languages and cultures are using it in more aspects of their daily live

Official announcement
GitHub Universe 2026: Evolving every layer of the stack
GitHub BlogJay Parikh
Our jobs as developers are changing. In a couple of years, we’ve gone from writing every line of code to working with AI assistants to orchestrating fleets of agents. But the goal hasn’t changed: ship completed software work. A feature, a bug fix, a security fix. Completed work,
Official announcement
Octoverse: Commits, pushes, reach new highs in 2026 as developers build with agents
GitHub BlogGitHub Staff
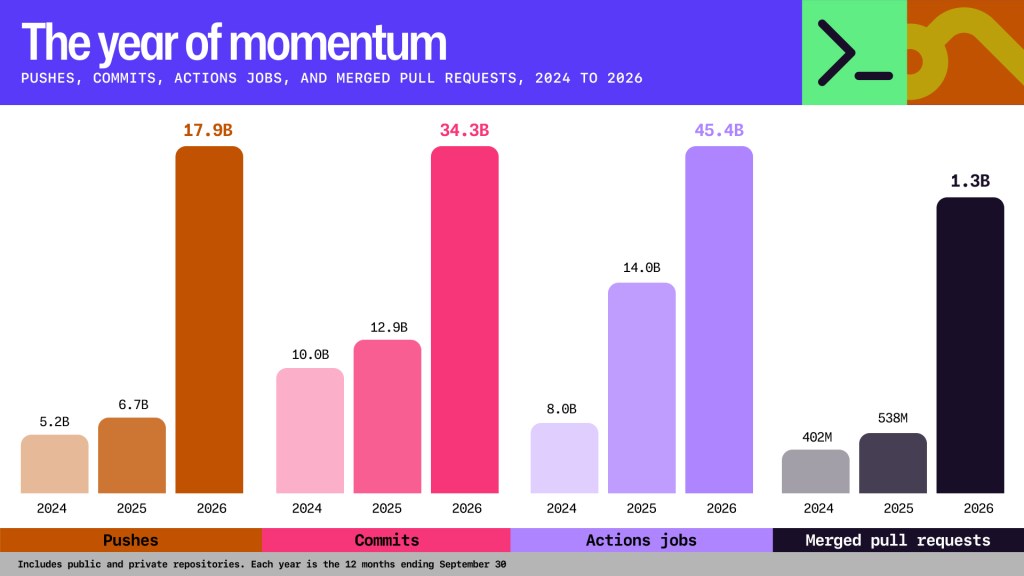
Developers pushed code to GitHub 17.9 billion times in the past 12 months, more than in 2024 and 2025 combined. Behind that number are developers building what interests them and what their communities need. In Nepal, one developer built a flood bulletin on GitHub Pages with veri
Official announcement
NVIDIA RTX Spark Windows Laptops Gain New Models, Agent Tools and Games
NVIDIA Newsroom
NVIDIA RTX Spark powers thin and light laptops built for everything that developers, creators and gamers do. RTX Spark laptops are now available from ASUS, Dell, HP, Lenovo, Microsoft and MSI. These powerful systems combine an NVIDIA Blackwell RTX GPU and an NVIDIA Grace CPU in a

Official announcement
NVIDIA RTX Spark Powers Neural Rendering and AI Characters in Games
NVIDIA Developer Blog
NVIDIA RTX Spark is a new Windows PC platform for AI development, creation, and gaming in slim laptops and compact desktops. Powered by an NVIDIA Blackwell RTX... NVIDIA RTX Spark is a new Windows PC platform for AI development, creation, and gaming in slim laptops and compact de
Official announcement
Legora is building the agentic operating system for legal work
OpenAI News
See how Legora uses OpenAI models, ChatGPT, and Codex to accelerate legal workflows, expand contract analysis, and free lawyers to focus on higher-value work.