A GPU cluster can pass every health check and still fail to run an AI workload. Even when every GPU, network link, and pod reports healthy, a 512-GPU training job can underperform or fail. The cause may be one slow GPU, a link that degrades under load, or a configuration that quietly routes traffic over a slower path. Operators may not discover the problem until hours into the run or until a customer files a ticket. Teams can then spend days bisecting the cluster to find the root cause while the capacity sits idle.
Official announcementNVIDIA Developer Blog
Validate GPU Cluster Readiness Before AI Workloads Land

From the official release
This is a short excerpt. Read the full announcement on the official source.
Continue on developer.nvidia.com → (opens in a new window)Related stories
Official announcement
AWS Security Hub now exports findings to S3 in CSV or JSON format
AWS What’s New
Today, AWS Security Hub announces support for exporting findings to Amazon S3 in CSV or JSON (OCSF) format. Security teams that need findings outside the console for use cases such as compliance reporting and audit evidence can now export findings from every findings page in the
Official announcement
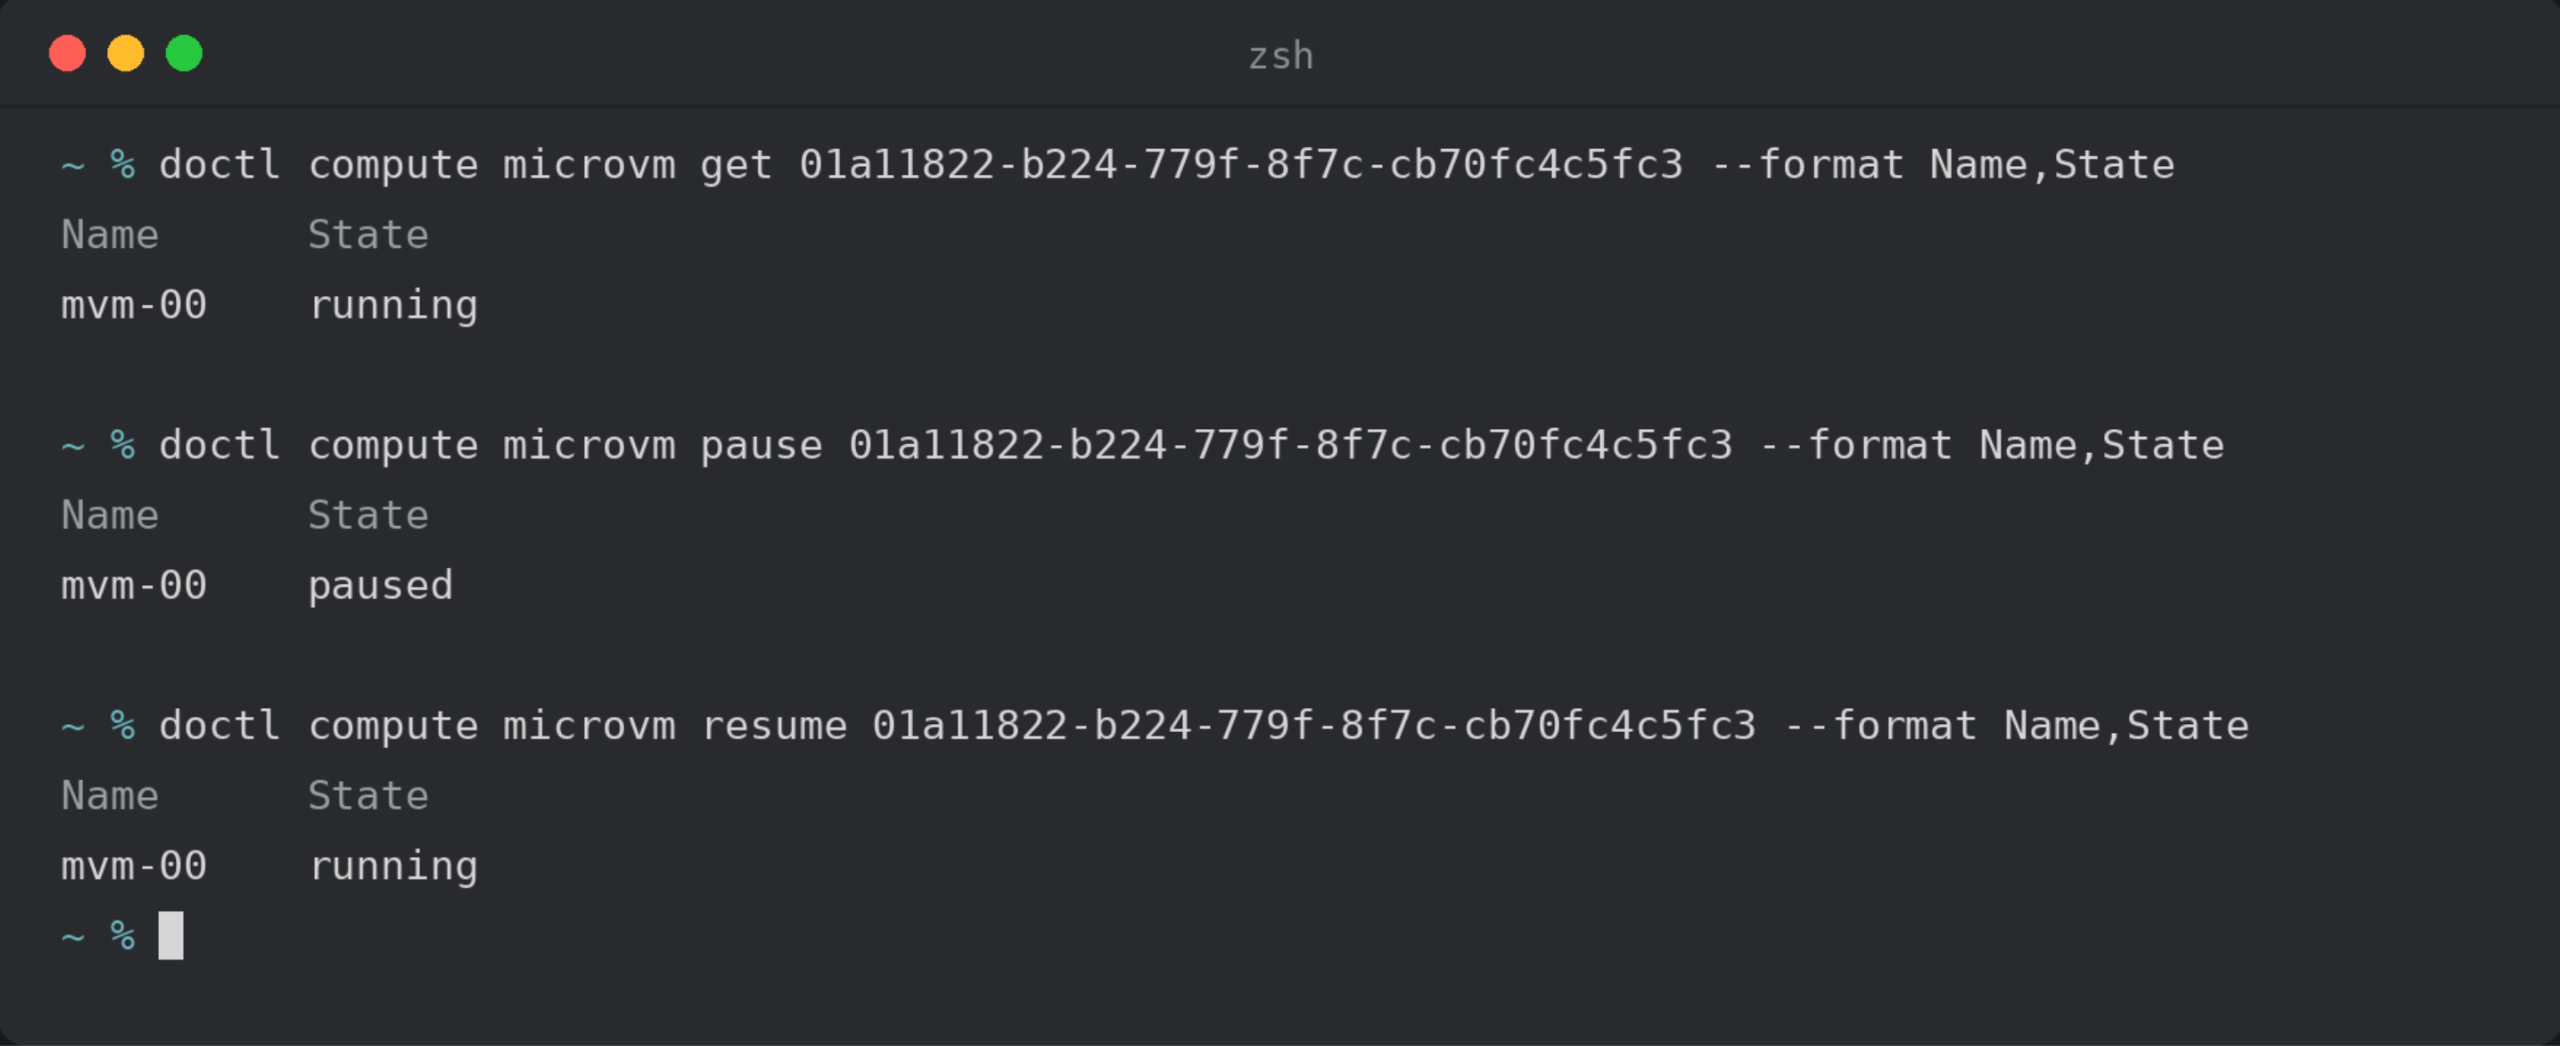
DigitalOcean MicroVMs: Fast, isolated compute for your AI agent infrastructure
DigitalOcean Blog
Coding-agent platforms, sandbox products, and code-execution services all need the same thing: isolated machines that start up fast, retain their state between bursts of work, and don’t consume compute when idle. If you build it yourself, you’ll have to lease compute capacity and
Official announcement
Amazon EC2 R8gd instances are now available in additional regions
AWS What’s New
Amazon Elastic Compute Cloud (Amazon EC2) R8gd instances are available in AWS European Sovereign Cloud (Germany) region. These instances feature up to 11.4 TB of local NVMe-based SSD block-level storage and are powered by AWS Graviton4 processors, delivering up to 30% better perf
Official announcement
Amazon EC2 R8g instances now available in additional regions
AWS What’s New
Starting today, Amazon Elastic Compute Cloud (Amazon EC2) R8g instances are available in the AWS European Sovereign Cloud (Germany) region. These instances are powered by AWS Graviton4 processors and deliver up to 30% better performance compared to AWS Graviton3-based instances.

Official announcement
Hack the World: Why hackathons are still the best place to learn to build
GitHub BlogEd Summers
Someone bursts through the door and announces, “There’s pizza!” Nearby, a team has duct tape and cardboard holding its prototype together. Another is debugging a model that won’t detect their movements. This is a common scene during hackathons, and for a lot of people they’re the
Official announcement
Building the Modern AI Infrastructure Stack with Cortex AI Gateway
Snowflake Blog
Learn more about AI cost governance . Dynamic model routing in Cortex AI Gateway: Pick the right model for each task Cost governance: Make every AI dollar count MCP and tool governance: Control what your agents can do Unified, governed inference: Use one endpoint for your agents