<p>Amazon SageMaker HyperPod now supports model caching, an inference optimization that pre-loads model weights and container images onto cluster nodes so pods start in seconds instead of minutes.</p>
<p>When running LLM inference at scale for workloads like chat assistants, agentic pipelines, RAG, and document analysis, cold start is a real bottleneck. Deployments and scale-out events spend most of their time downloading container images and model weights. As model size increases, this gets worse, with large models taking tens of minutes before they can serve traffic.</p>
<p>Model caching solves this with two independent capabilities. The weights cache stores model weights on local NVMe so pods read from fast local storage instead of pulling from S3 or FSx over the network. The image cache pre-pulls the container image so pods skip the ECR download entirely. If a pod lands on a node without a warm cache, it falls back to pulling from the original source automatically, so there is no risk of pods getting stuck or failing.</p>
<p>Benchmarks across models from 57 GB to 145 GB show around 60% faster scale-out, and the image cache cuts over two minutes of image-pull time (97% reduction). The benefit grows with model size while retaining the reliability of the original source path.</p>
<p>Customers enable model caching through the HyperPod Inference Operator by adding a modelCacheConfig section to their InferenceEndpointConfig or JumpStartModel resource. The operator handles the full lifecycle with no manual setup or cleanup.</p>
<p>Model caching is now generally available in all regions where SageMaker HyperPod is available. To get started, see the <a href="https://docs.aws.amazon.com/sagemaker/latest/dg/sagemaker-hyperpod-model-deployment-model-caching.html">SageMaker HyperPod documentation</a>.</p>
<p> </p>
Amazon SageMaker HyperPod now supports model caching for faster inference autoscaling and reduced cold starts
Amazon SageMaker HyperPod now supports model caching, an inference optimization that pre-loads model weights and container images onto cluster nodes so pods start in seconds instead of minutes. When running LLM inference at scale for workloads like chat assistants, agentic pipeli
Related stories
Migrating the GitHub Copilot runtime to Rust, using Copilot
GitHub BlogStephen Toub
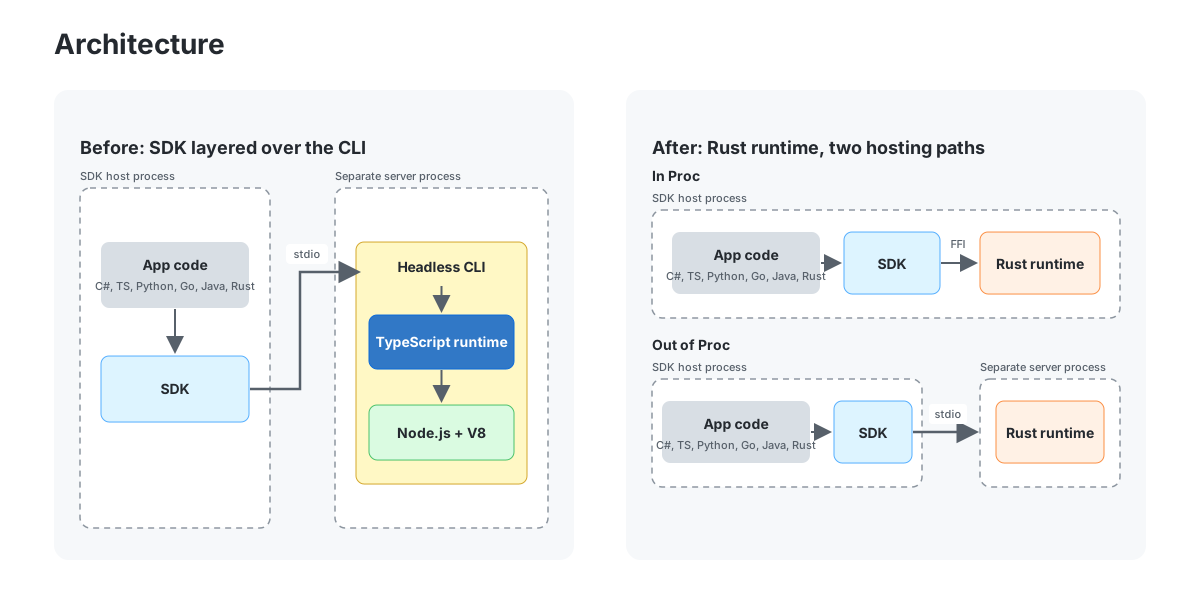
The GitHub Copilot CLI , GitHub Copilot app , and GitHub Copilot SDK are all backed by the Copilot agent runtime, an agentic harness that can be embedded into applications and services. It was originally written in TypeScript on Node.js and the V8 JavaScript engine for what is no

How to Use AI Agents to Prepare 3D Scenes for Simulation
NVIDIA Developer Blog
Agentic AI workflows can be used to prepare and validate digital twins for physical AI systems. Agents can inspect 3D scenes, author simulation-relevant data in... Agentic AI workflows can be used to prepare and validate digital twins for physical AI systems. Agents can inspect 3

TensorRT Edge-LLM Completes the MLPerf Edge Agentic Benchmark 6.4x Faster on Jetson AGX Thor
NVIDIA Developer Blog
AI agents are moving from cloud data centers to vehicles, robots, and other edge devices. Unlike a chatbot that answers a single prompt, an agent works through... AI agents are moving from cloud data centers to vehicles, robots, and other edge devices. Unlike a chatbot that answe
"Regex for Rows": Simplifying Pattern Detection in SQL with MATCH_RECOGNIZE
Databricks Blog
Imagine you work in cybersecurity and you have a table that tracks login attempts...

Translating CUDA Tile Operations from Python to Rust Using Agentic AI
NVIDIA Developer Blog
cuTile Rust (cutile-rs) is a tile-based system for safe, idiomatic GPU kernel authoring in the Rust programming language. Extending the Rust ownership model to... cuTile Rust () is a tile-based system for safe, idiomatic GPU kernel authoring in the Rust programming language. Exte

Dell PowerStore AI Skills: Smarter Storage Operations
Dell Blog
See how AI skills with pstcli let admins manage Dell PowerStore in natural language – with faster health checks, performance analysis, and secure operations.