How can a 30B-parameter model activate only 3B parameters per token, and still use the capacity of the larger model? Nemotron 3.5 Lightning illustrates the... How can a 30B-parameter model activate only 3B parameters per token, and still use the capacity of the larger model? Nemo
Official announcementNVIDIA Developer Blog
Dense vs. MoE Models: Active Parameters, Throughput, and When to Choose Each

Related stories
Official announcement
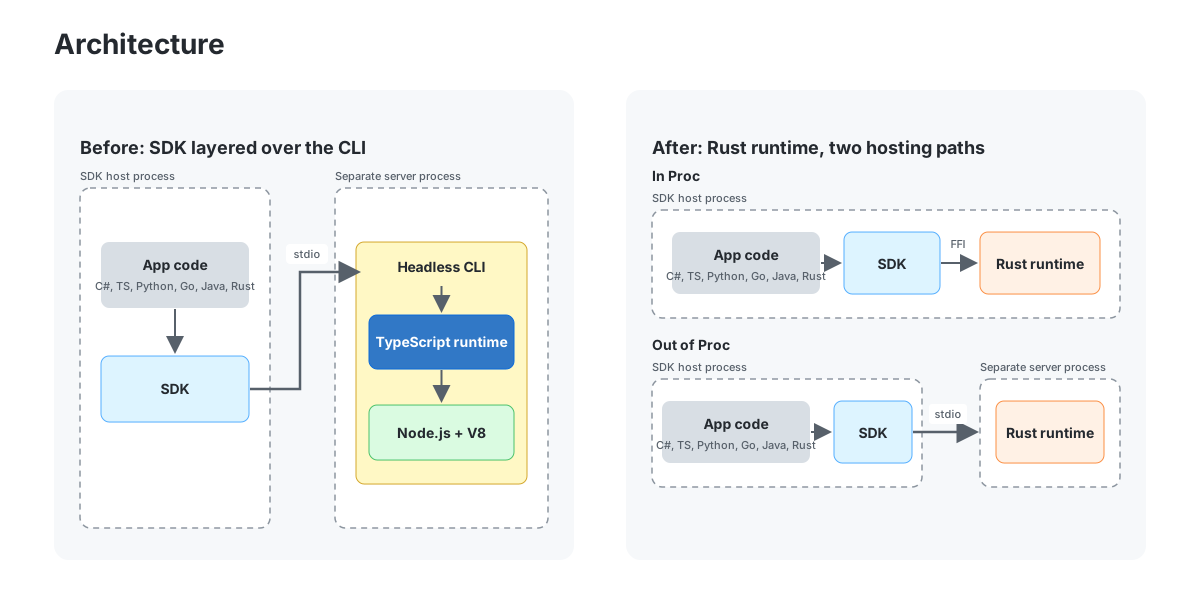
Migrating the GitHub Copilot runtime to Rust, using Copilot
GitHub BlogStephen Toub
The GitHub Copilot CLI , GitHub Copilot app , and GitHub Copilot SDK are all backed by the Copilot agent runtime, an agentic harness that can be embedded into applications and services. It was originally written in TypeScript on Node.js and the V8 JavaScript engine for what is no

Official announcement
How to Use AI Agents to Prepare 3D Scenes for Simulation
NVIDIA Developer Blog
Agentic AI workflows can be used to prepare and validate digital twins for physical AI systems. Agents can inspect 3D scenes, author simulation-relevant data in... Agentic AI workflows can be used to prepare and validate digital twins for physical AI systems. Agents can inspect 3

Official announcement
TensorRT Edge-LLM Completes the MLPerf Edge Agentic Benchmark 6.4x Faster on Jetson AGX Thor
NVIDIA Developer Blog
AI agents are moving from cloud data centers to vehicles, robots, and other edge devices. Unlike a chatbot that answers a single prompt, an agent works through... AI agents are moving from cloud data centers to vehicles, robots, and other edge devices. Unlike a chatbot that answe
Official announcement
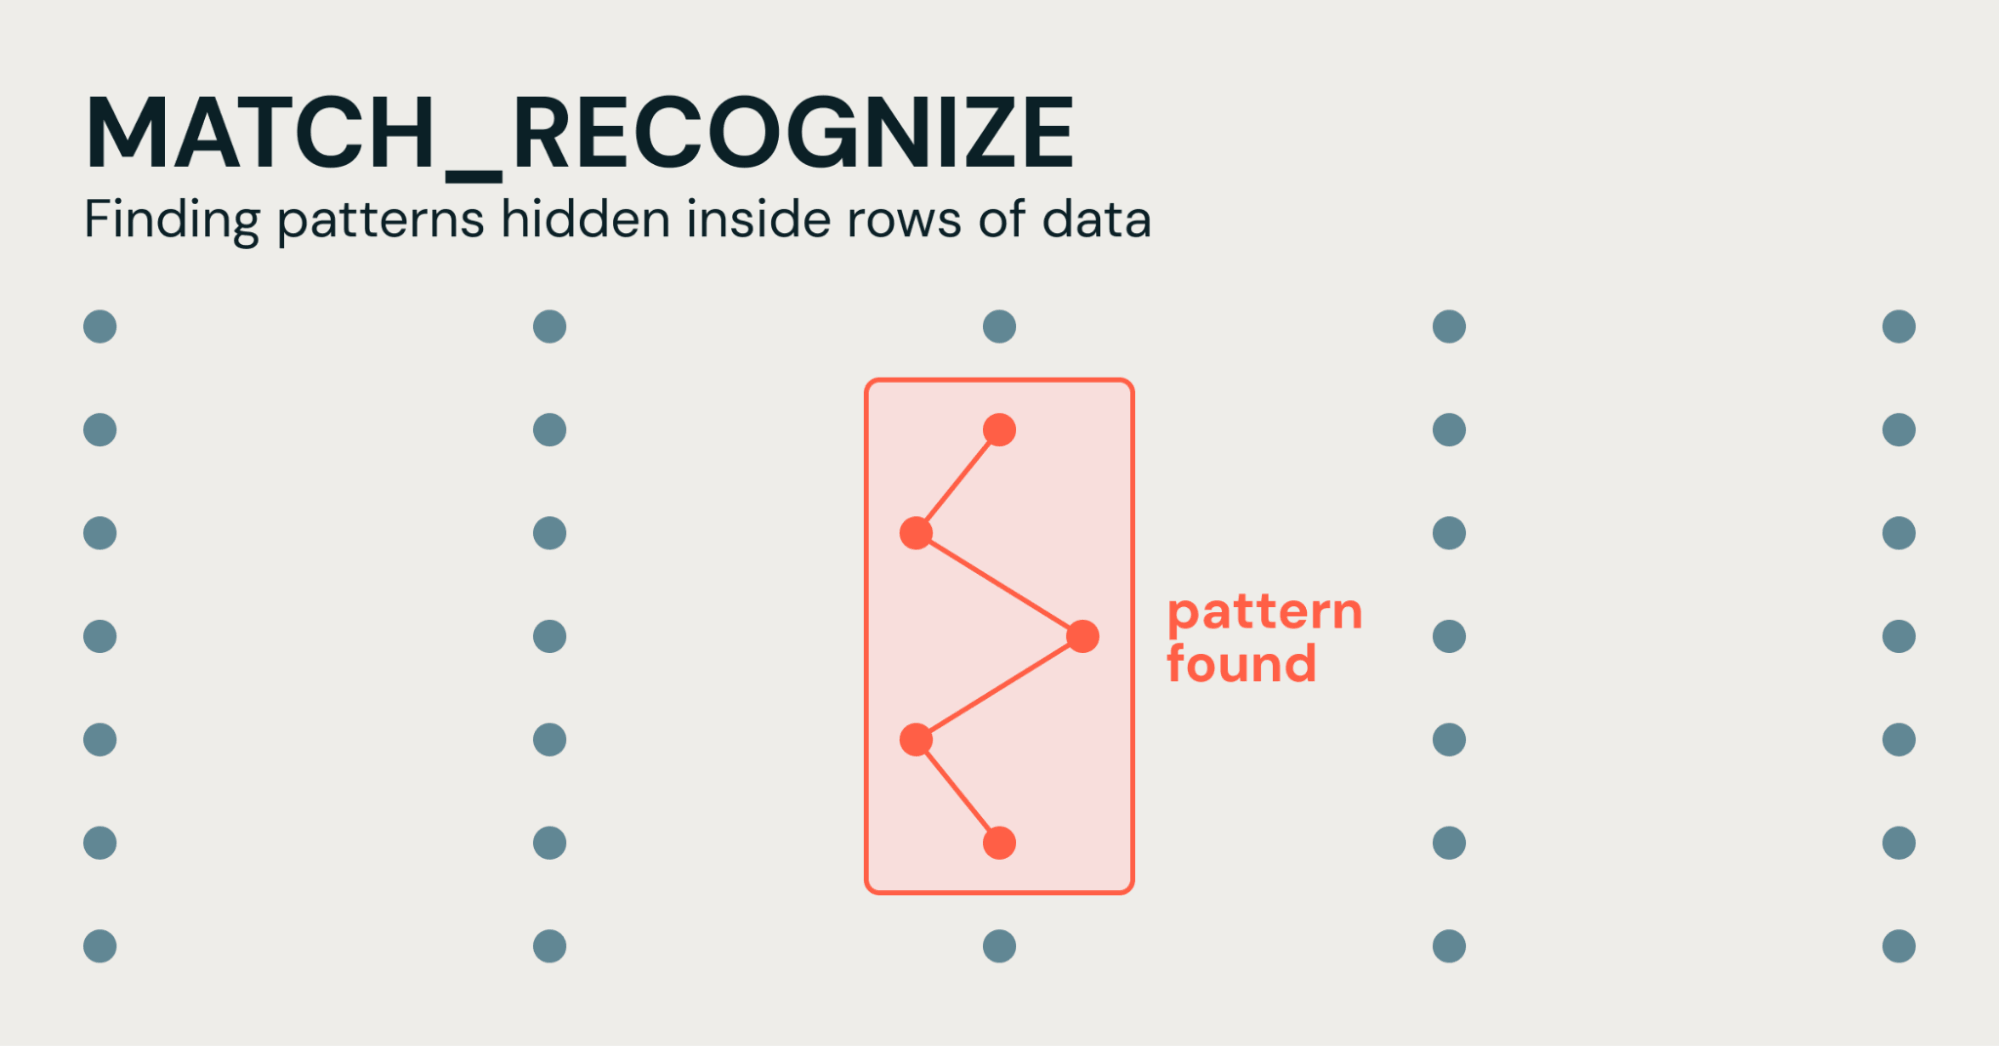
"Regex for Rows": Simplifying Pattern Detection in SQL with MATCH_RECOGNIZE
Databricks Blog
Imagine you work in cybersecurity and you have a table that tracks login attempts...

Official announcement
Translating CUDA Tile Operations from Python to Rust Using Agentic AI
NVIDIA Developer Blog
cuTile Rust (cutile-rs) is a tile-based system for safe, idiomatic GPU kernel authoring in the Rust programming language. Extending the Rust ownership model to... cuTile Rust () is a tile-based system for safe, idiomatic GPU kernel authoring in the Rust programming language. Exte
Official announcement
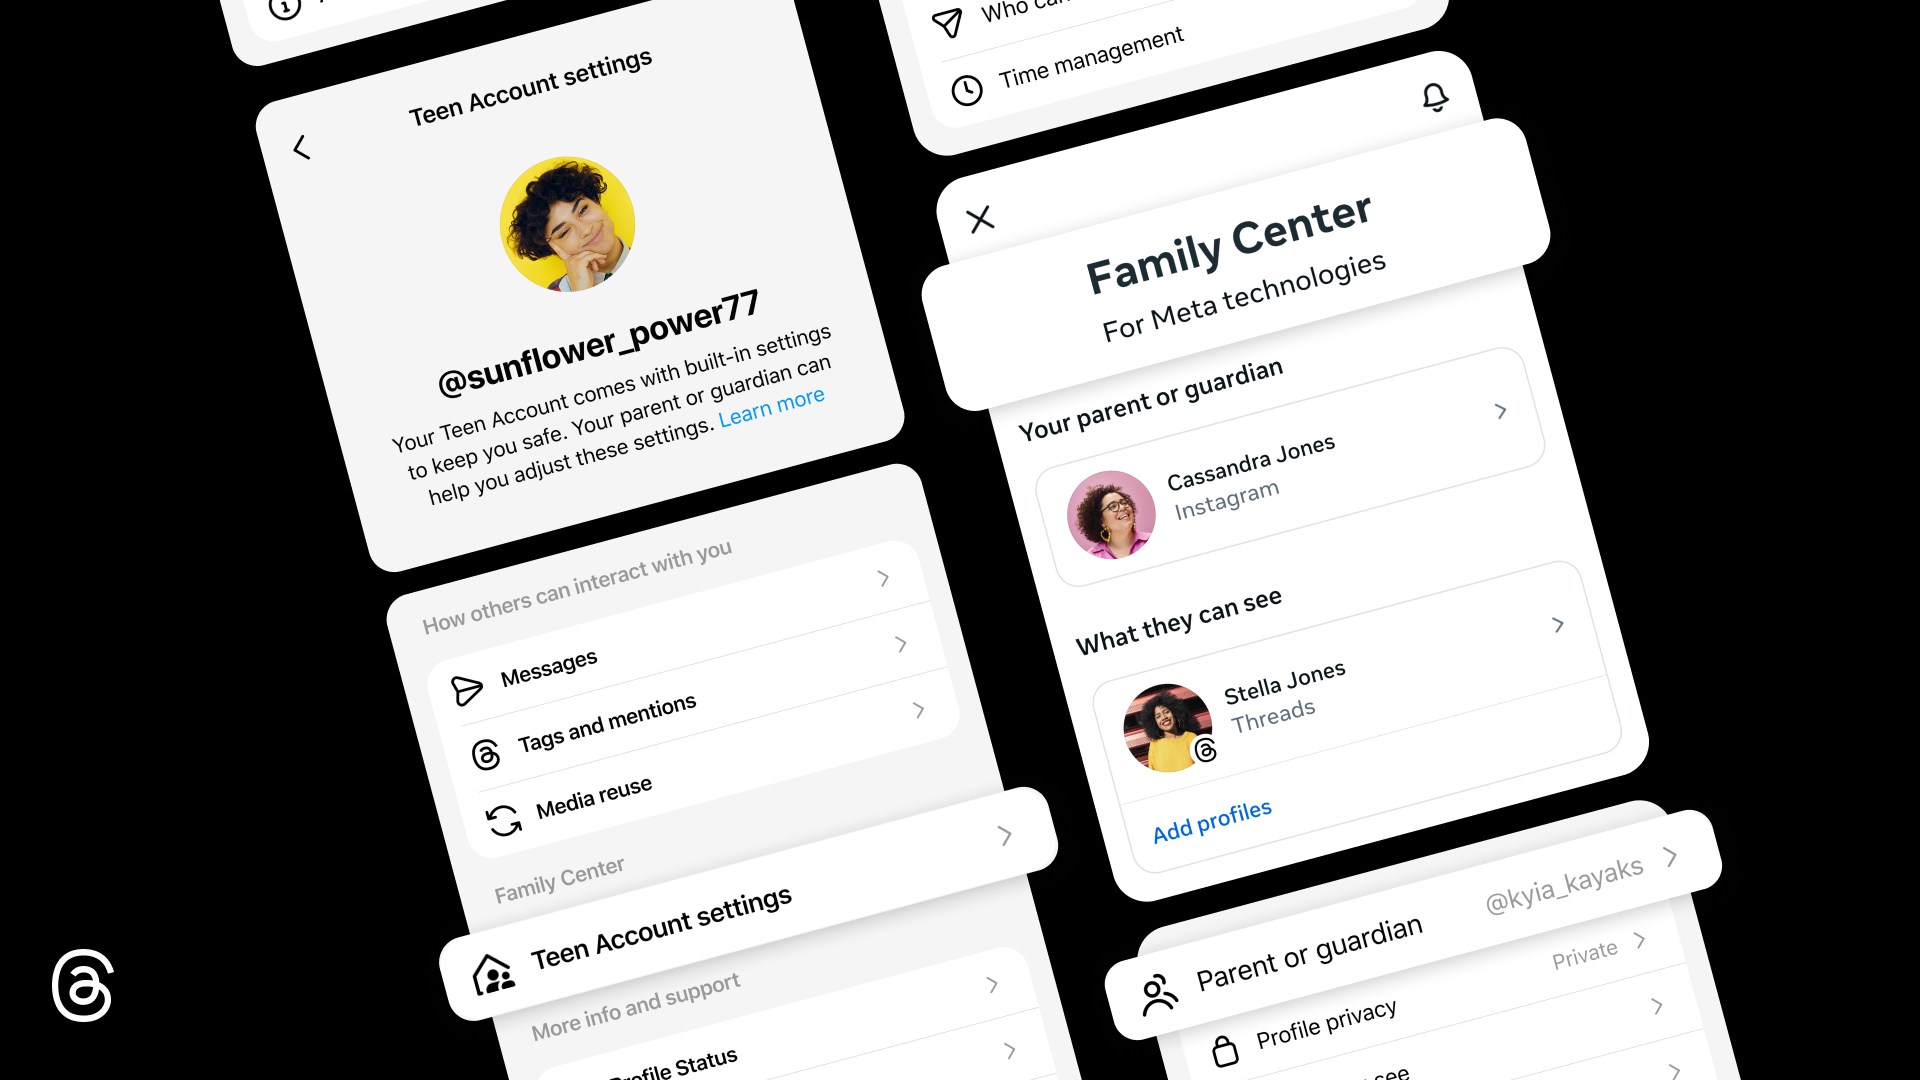
Threads Introduces Parental Supervision for Teens in APAC
Meta NewsroomFacebook
As part of our ongoing commitment to providing parents with helpful tools to support their teens across Meta’s apps, we’re bringing parental supervision to Threads. Starting this week in Asia Pacific countries, parents and guardians in Family Center will have visibility and contr